Automated Software Engineering You Can Trust
Translate, verify, and optimize complex software, with independent evidence the output works as intended
why customers use code metal
Stop choosing betweenmoving fast and proving it works.
Legacy modernization
Modeling and simulation
Optimize performance
Prototype to production fast
trusted by
One platform, anycode-to-code task
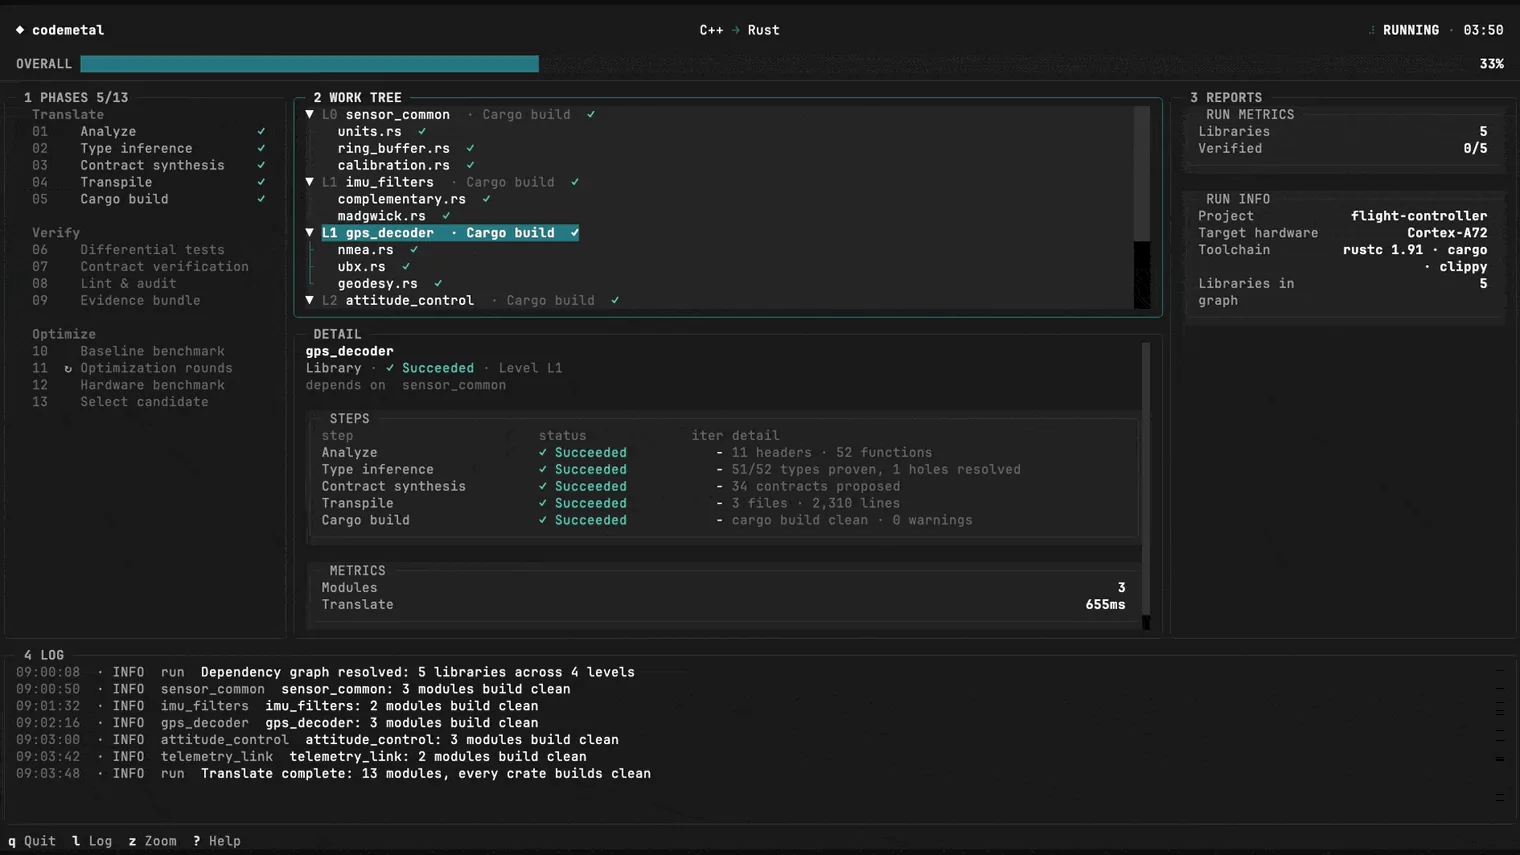
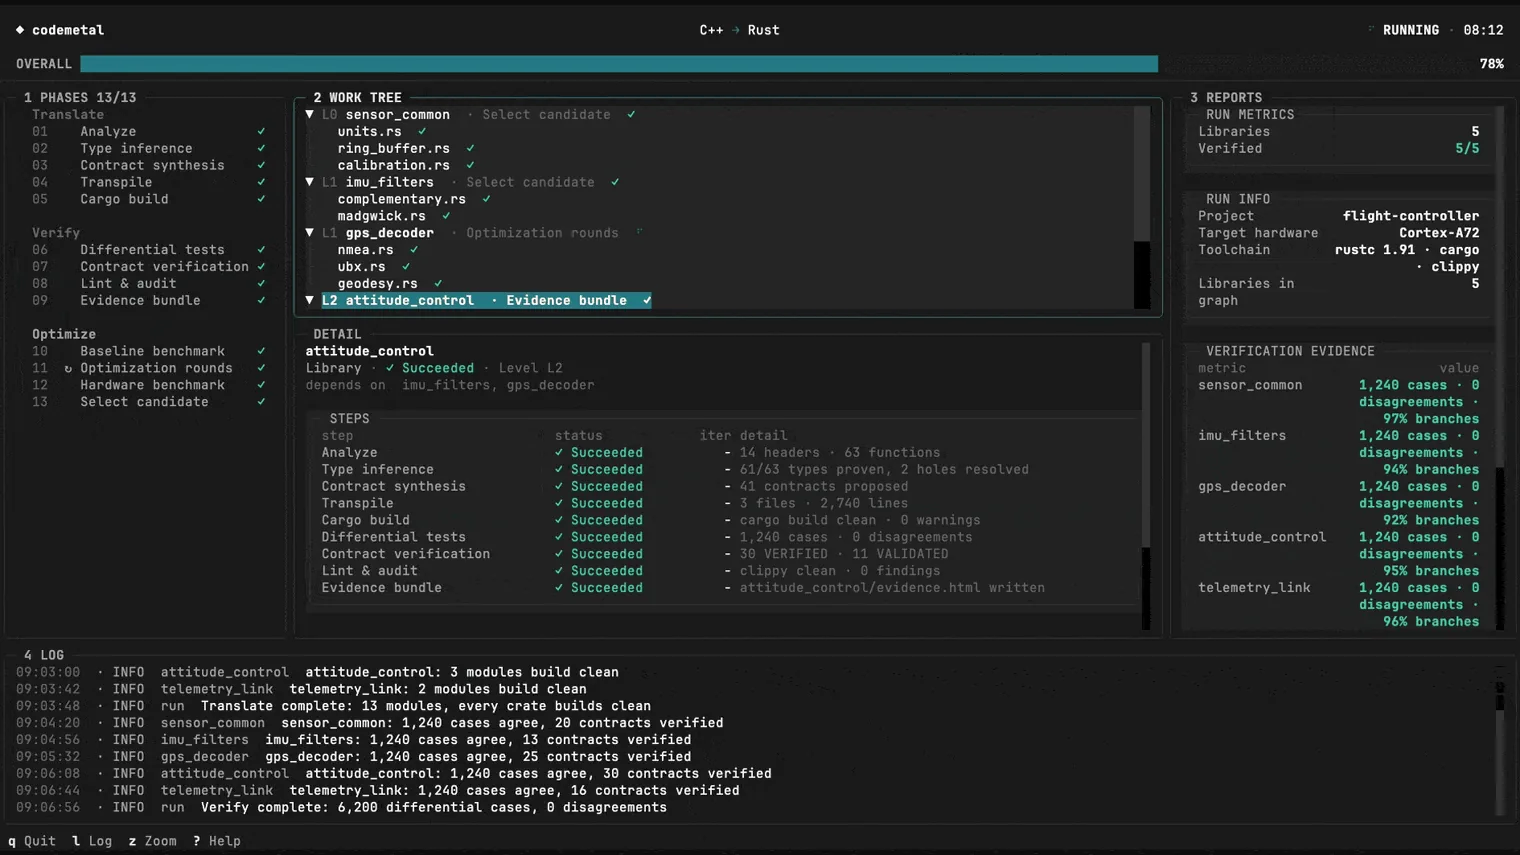
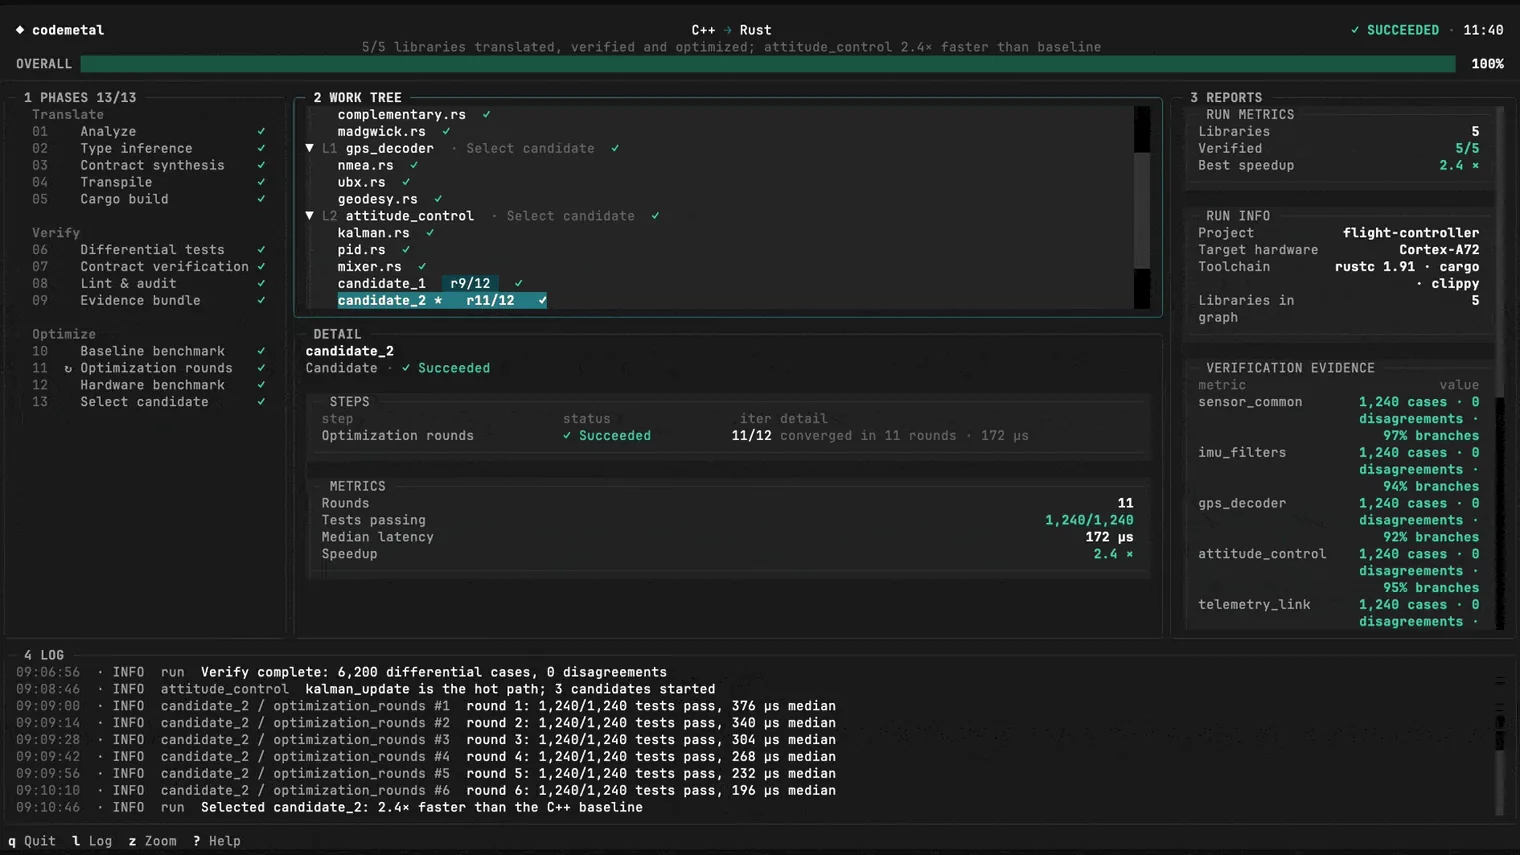
Code Metal automates complete code-to-code engineering workflows, from understanding an existing system to delivering verified software optimized for its target hardware.
The Code Metal Approach
Trusted & Efficient
We match models to the work.
We benchmark models on engineering tasks and select for capability, efficiency, and each customer's deployment requirements.
We keep AI within bounds.
We constrain what it can do against explicit requirements, keeping the work focused and its output checkable.
We verify independently.
We use formal methods independent of the model to verify defined properties of proposed changes, giving engineers evidence they can inspect.
We keep engineers in charge.
We automate repeatable work so engineers can shape the system, weigh tradeoffs, and decide what ships.
The Research BehindTrustworthy AI
Methods, benchmarks, and results from our research team
all researchfeatured
Back in the Race: US Open-Weight Models Closing the Performance Gap
On an internal benchmark translating C++ to Rust, Muse Spark Open reached the top tier of judged translation quality, and strong results across four US-developed model families point to more promising options for teams that need US-developed models to run on their own infrastructure.
read on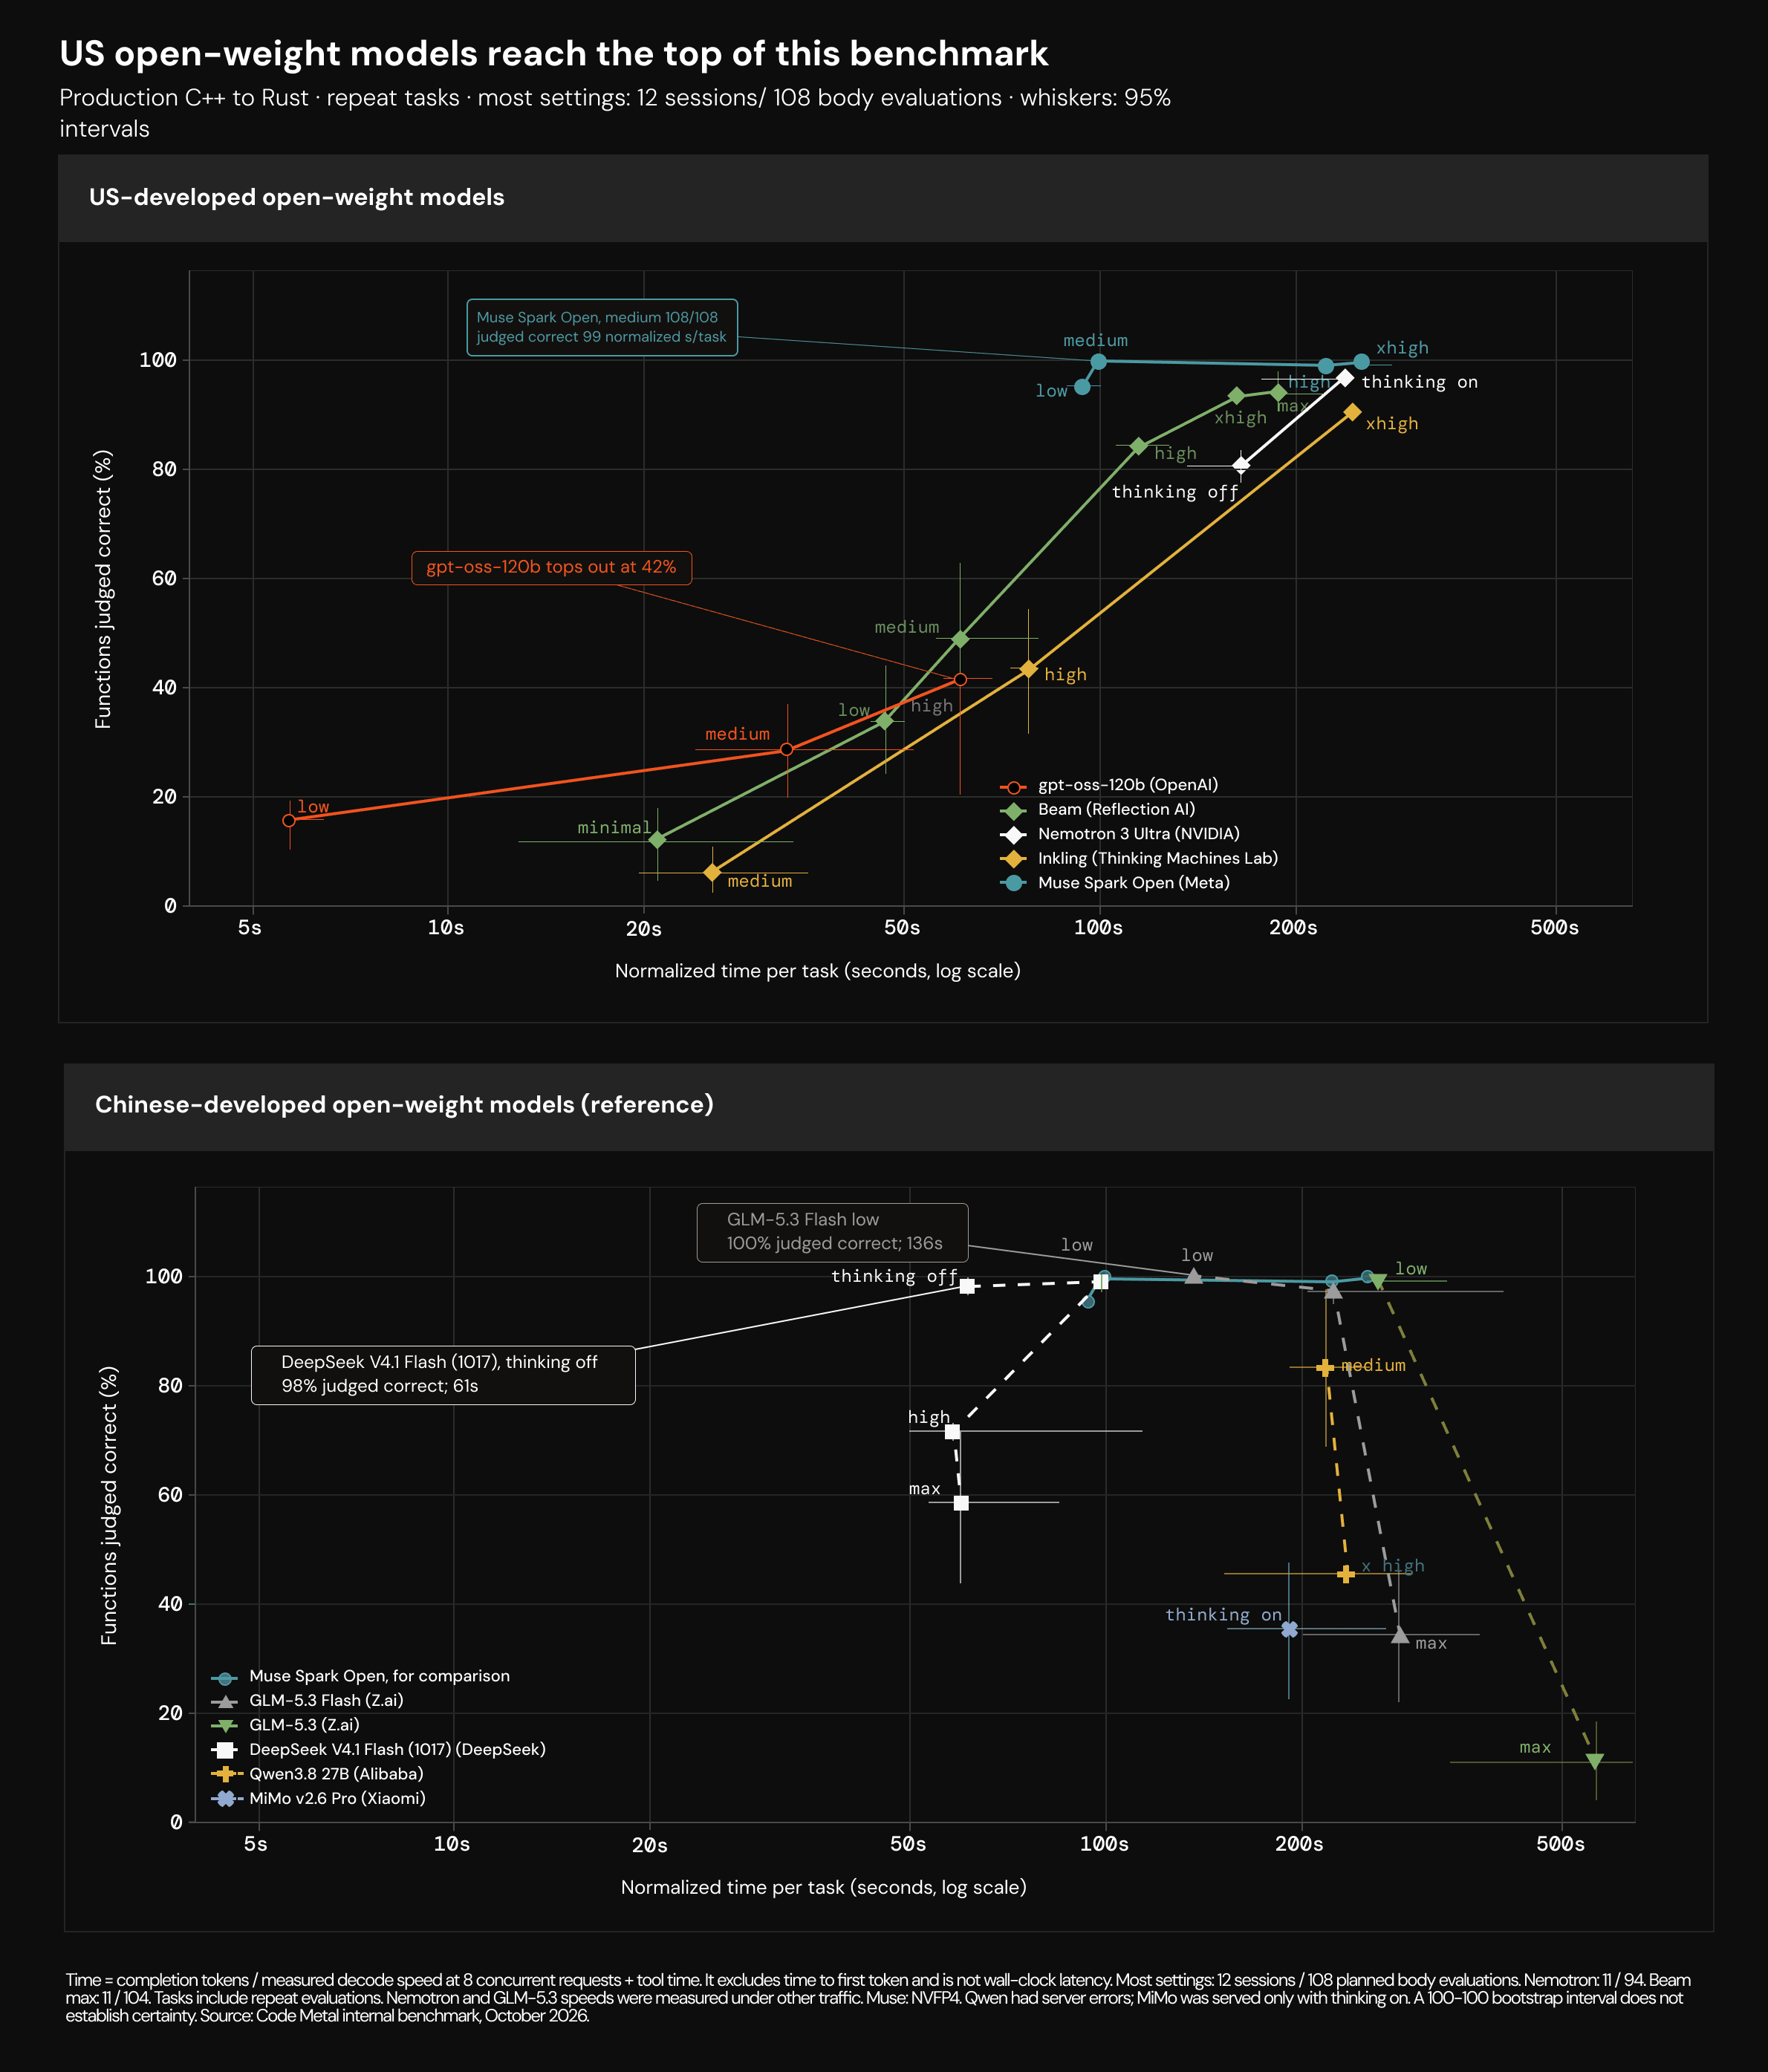
Latest News & Updates
[company]
Announcing the Code Metal Forge Hackathon 2026 — Operation Lost and Found
[company]
Introducing the Verified Code Translation Research Awards
[press]
Code Metal Scores $80M OTA for WarMatrix
[press]
Code Metal Lands $80 Million Pentagon Deal to Modernize Military Wargaming
[company]
Code Metal Awarded $80M Department of War Agreement to Advance AI-Enabled Modeling and Simulation
We’re looking for people drawn to hard problems, high standards, and work of consequence
explore careers